01
What is an AI safety evaluation?
An AI safety evaluation is a structured test of how an AI system could fail or cause harm, run before release and repeated after changes. It measures specific risks, such as false answers, leaked personal data or misuse, against criteria set in advance, so that a release decision rests on evidence rather than impressions.
Definitions vary in emphasis. Japan’s AI Safety Institute defines an AI safety evaluation as the “determination of whether an AI system is appropriate in terms of AI Safety perspective”, and its guide organises the work into ten evaluation perspectives, from control of toxic output and prevention of misinformation to privacy protection, robustness and verifiability 1. Georgetown’s Center for Security and Emerging Technology calls evaluations “the best tool we have to assess and understand potential risks”, while stressing that they measure proxies for real-world risk 2.
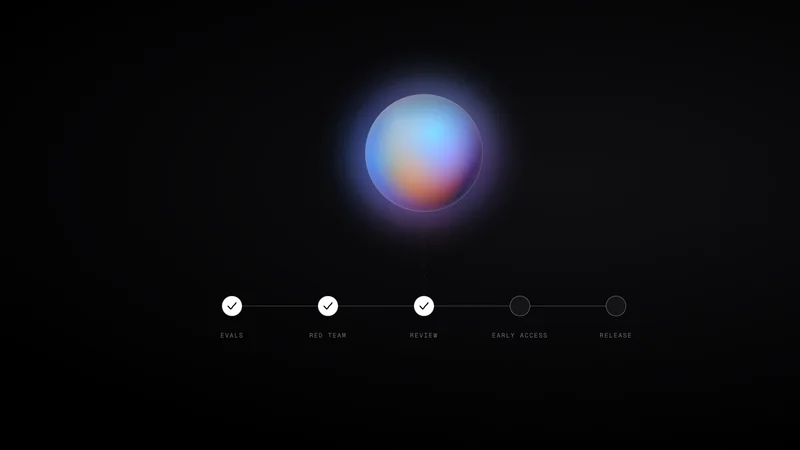
In the NIST AI Risk Management Framework, evaluation sits within four functions, govern, map, measure and manage, and the framework stresses test, evaluation, verification and validation “throughout an AI lifecycle” 3. Evaluating a language model differs from testing ordinary software in one important way: its behaviour is statistical, so an evaluation reports rates over many attempts rather than a single pass or fail. Figure 1 follows one evaluation from the risks it covers to a release decision.
- Decide what could go wrong, and set the bar first. Each risk gets a pass criterion before any test runs, so the results can’t quietly move the bar.
- Build test sets for each risk. Benchmarks have known answers, red-team attacks look for failures on purpose, and canaries are made-up details that reveal a leak if they reappear. Test sets are kept out of training data.
- Run every test on the whole system, several times. The system prompt, retrieval and tools change what a model does, and sampled outputs vary from run to run.
- Score each output as a pass or a fail. Automatic checks are fast, model graders scale, and people judge what neither can. Each has blind spots of its own.
- Compare the results with the bar set in step 1. This run falls short, so the system is fixed and every test runs again, because a fix for one failure can cause another.
- Release only when the bar is met, and publish the results. A pass shows that the system met the tests that were run. It can’t show that no other failure exists.
02
What is the difference between model and system evaluations?
A model evaluation tests the trained model on its own; a system evaluation tests the whole product people use, including its system prompt, retrieval, tools, filters and interface. Both are needed, because many failures and many safeguards live outside the model.
Most published benchmarks are model evaluations. HELM, an effort to standardise them, measured 30 language models on 16 core scenarios with seven metrics, accuracy, calibration, robustness, fairness, bias, toxicity and efficiency, so that qualities other than accuracy weren’t neglected 4. CSET draws a similar line between model safety evaluations, which assess a model’s outputs alone, and contextual evaluations, which assess how models affect real-world outcomes 2.
Weidinger and colleagues argue that capability evaluations, the main current approach, are not enough on their own, because “context determines whether a given capability may cause harm”; their framework adds layers for human interaction and for systemic impact 5. A system can be safer than its model, when code around the model blocks a failure, or less safe, when retrieval exposes the model to an attack it would otherwise never see. Indirect prompt injection, for example, can only be tested on a system that retrieves content.
03
What is red-teaming, and who does it?
Red-teaming is deliberately trying to make a system fail or misbehave, the way an attacker or a careless user might. People do it by hand, and language models can do it at a scale people can’t, by writing test cases for another model.
Human red-teaming is the established method. Ganguli and colleagues red-teamed models of three sizes, with 2.7, 13 and 52 billion parameters, and four types, and released 38,961 red-team attacks for others to study. They found that models trained with reinforcement learning from human feedback became harder to red-team as they grew, while the other types showed a flat trend with size 6.
Automated red-teaming uses one model to test another. Perez and colleagues used a language model to generate test questions and a classifier to judge the replies, “uncovering tens of thousands of offensive replies in a 280B parameter LM chatbot”, along with other harms such as leakage of private training data 7. Automated methods can produce far more test cases than people can write; people still find the failures that depend on judgement, context or creativity, so serious evaluations use both.
A red-team result shows the failures that were found, not the ones nobody tried. Shevlane and colleagues distinguish “dangerous capability evaluations”, which ask what a model can do, from “alignment evaluations”, which ask how inclined it is to use those capabilities for harm 8. Red-teaming contributes evidence to both.
04
How are calibration and honesty evaluated?
Calibration is evaluated by comparing a model’s confidence with how often it is right; honesty is evaluated by checking whether it says only what it has grounds to say, including ‘I don’t know’ when it should. Both are measured on questions with known answers.
For calibration, an evaluation groups answers by the model’s confidence and checks the accuracy in each group: answers given with 70% confidence should be right about 70% of the time. Guo and colleagues found that modern neural networks are often poorly calibrated 9, while Kadavath and colleagues found large language models well calibrated on multiple-choice and true-or-false questions in the right format, and able to estimate whether they know an answer 10.
Honesty evaluations ask different questions. TruthfulQA tests whether a model repeats common misconceptions, with 817 questions written so that some people would answer them falsely 11. Other tests check whether a model admits uncertainty instead of guessing, and whether each citation supports the sentence it is attached to. How a benchmark is scored shapes what it rewards: Kalai and colleagues argue that grading answers only as right or wrong rewards confident guessing over admitting uncertainty 12. Our explainer on why AI makes things up covers the underlying problem.
05
What is a privacy leakage audit?
A privacy leakage audit tests whether a system reveals personal information it shouldn’t, whether memorised from training data or carried over from its context. The standard technique plants made-up secrets, called canaries, and measures whether they come back out.
The canary method comes from Carlini and colleagues, who inserted artificial secrets into training data and measured how readily the trained model reproduced them, giving a quantitative test for unintended memorisation 13. The same idea works for a system’s context: seed a test profile with distinctive, made-up personal details, run tasks, and search every output and every outbound request for those details.
Not every leak comes from memory. Mireshghallah and colleagues tested whether models keep information to its proper context, drawing on the theory of contextual integrity, and found that two of the most capable models they tested revealed private information in contexts where people would not, 39% and 57% of the time; the leakage persisted even with privacy-inducing prompts 14. Assistants that hold personal context and act for a person need this kind of test, because the leak happens in what the system says or sends, not in its training data.
06
What is a release gate?
A release gate is a checkpoint a system must pass before it reaches more people, with pass criteria written down before testing begins. If the system fails, the release waits until the problem is fixed and the tests are run again.
The NIST AI RMF makes the decision explicit. Under its Manage function, “A determination is made as to whether the AI system achieves its intended purposes and stated objectives and whether its development or deployment should proceed”, and under Measure, a system to be deployed is “demonstrated to be safe, its residual negative risk does not exceed the risk tolerance, and it can fail safely, particularly if made to operate beyond its knowledge limits” 3.
Gates usually run in stages: internal evaluations, then adversarial testing, then a limited release, then wider availability. Staged release has precedent in AI: Solaiman and colleagues describe releasing a language model in stages, which left time between releases to analyse its risks and benefits 15. Three kinds of criteria are common: a threshold, the minimum acceptable result in an area; no regressions, meaning nothing gets worse than in the previous version without a stated reason; and hard stops, failures that block a release however good everything else is.
Setting criteria first matters because criteria written after seeing results tend to drift towards whatever the system already does. Publishing them with the results lets others check the decision. Model cards, proposed by Mitchell and colleagues, established the practice of reporting evaluation results alongside a model’s intended use 16; our explainer on model cards and system cards describes them.
07
What can’t evaluations tell you?
An evaluation can show that a failure exists, but never that none does. It measures the risks someone thought to test, on the inputs they chose, at the time they ran it.
- Coverage. A passed test shows only what was tested. Red-teaming finds what its people and models think to try, and a new attack can defeat a system that passed every existing test.
- Contamination. A public test set can leak into later training data. Magar and Schwartz found that models trained on such contaminated data sometimes exploit it to score better on the leaked examples, and sometimes memorise it without benefiting 17.
- Proxies. Evaluations measure stand-ins for real-world risk, so a good result may not carry over to real use 2.
- Graders. Model graders have biases of their own. Zheng and colleagues found position, verbosity and self-enhancement biases in language models used as judges: a preference for the answer shown first, for longer answers, and for answers like their own 18.
- Variation. Outputs vary between runs and between devices, so results have to be reported as rates over repeated runs, with the sample size and the date.
- Self-assessment. Developers who evaluate their own systems have a conflict of interest. Brundage and colleagues analyse mechanisms, including third-party auditing and red-teaming exercises, for making developers’ claims verifiable 19.
When results are published, look for the method, the sample size, the date, which direction of the score is better, and what was left out.
08
How do we intend to evaluate Brello Super Intelligence?
Brello Super Intelligence is in development. This section describes design intent, not results. No evaluation of Brello SI has been run.
We intend to test each new capability of Brello Super Intelligence before release, against criteria set before testing begins, and to publish what we find. The plan, set out in ‘Evaluate first, then ship’, applies the methods above to six areas and four release gates.
The Brello Charter makes this a commitment: “We will evaluate each new capability before release, and publish what we find” (Charter v1.0, commitment 04). Brello 1.0 has no server, so we never see its conversations, and the sealed compute we’re designing for Brello SI is intended to keep nothing and to allow no human access. Early access will therefore tell us only what participants choose to report, so most of the evidence has to be gathered before release. Our safety page summarises the planned areas alongside the guards in Brello 1.0, and the plan’s open questions include how to set thresholds for calibration and privacy leakage before any results exist.
References
Reviewed . Web pages were checked on that date.
- Japan AI Safety Institute (2025). “Guide to Evaluation Perspectives on AI Safety (Version 1.10).” Published 28 March 2025. Version 1.20, in Japanese, was published on 7 July 2026. Accessed 5 October 2026. aisi.go.jp/
assets/ pdf/ ai_safety_eval_v1.10_en.pdf - Ji, J., Venkatram, V. and Batalis, S. (2025). “AI Safety Evaluations: An Explainer.” Center for Security and Emerging Technology, Georgetown University, 28 May 2025. Accessed 5 October 2026. cset.georgetown.edu/
article/ ai-safety-evaluations-an-explainer - National Institute of Standards and Technology (2023). “Artificial Intelligence Risk Management Framework (AI RMF 1.0).” NIST AI 100-1, January 2023. doi.org/
10.6028/ NIST.AI.100-1 - Liang, P. et al. (2023). “Holistic Evaluation of Language Models.” Transactions on Machine Learning Research. arxiv.org/
abs/ 2211.09110 - Weidinger, L. et al. (2023). “Sociotechnical Safety Evaluation of Generative AI Systems.” arXiv preprint. arxiv.org/
abs/ 2310.11986 - Ganguli, D. et al. (2022). “Red Teaming Language Models to Reduce Harms: Methods, Scaling Behaviors, and Lessons Learned.” arXiv preprint. arxiv.org/
abs/ 2209.07858 - Perez, E. et al. (2022). “Red Teaming Language Models with Language Models.” Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing (EMNLP 2022). arxiv.org/
abs/ 2202.03286 - Shevlane, T. et al. (2023). “Model evaluation for extreme risks.” arXiv preprint. arxiv.org/
abs/ 2305.15324 - Guo, C. et al. (2017). “On Calibration of Modern Neural Networks.” Proceedings of the 34th International Conference on Machine Learning (ICML 2017). arxiv.org/
abs/ 1706.04599 - Kadavath, S. et al. (2022). “Language Models (Mostly) Know What They Know.” arXiv preprint. arxiv.org/
abs/ 2207.05221 - Lin, S. et al. (2022). “TruthfulQA: Measuring How Models Mimic Human Falsehoods.” Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (ACL 2022). arxiv.org/
abs/ 2109.07958 - Kalai, A. T. et al. (2025). “Why Language Models Hallucinate.” arXiv preprint. arxiv.org/
abs/ 2509.04664 - Carlini, N. et al. (2019). “The Secret Sharer: Evaluating and Testing Unintended Memorization in Neural Networks.” Proceedings of the 28th USENIX Security Symposium. arxiv.org/
abs/ 1802.08232 - Mireshghallah, N. et al. (2024). “Can LLMs Keep a Secret? Testing Privacy Implications of Language Models via Contextual Integrity Theory.” International Conference on Learning Representations (ICLR 2024). arxiv.org/
abs/ 2310.17884 - Solaiman, I. et al. (2019). “Release Strategies and the Social Impacts of Language Models.” arXiv report. arxiv.org/
abs/ 1908.09203 - Mitchell, M. et al. (2019). “Model Cards for Model Reporting.” Proceedings of the Conference on Fairness, Accountability, and Transparency (FAT* 2019). arxiv.org/
abs/ 1810.03993 - Magar, I. and Schwartz, R. (2022). “Data Contamination: From Memorization to Exploitation.” Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (ACL 2022). arxiv.org/
abs/ 2203.08242 - Zheng, L. et al. (2023). “Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena.” NeurIPS 2023 Datasets and Benchmarks Track. arxiv.org/
abs/ 2306.05685 - Brundage, M. et al. (2020). “Toward Trustworthy AI Development: Mechanisms for Supporting Verifiable Claims.” arXiv preprint. arxiv.org/
abs/ 2004.07213
Version history
- 1.0First published.